Free sample lesson · Scaling LLM Applications and Infrastructure
Inference Optimization
How do you handle a million users without breaking the bank?
Lesson 1 of the Wondering course Scaling LLM Applications and Infrastructure
Why Inference Needs Optimization
Inference is the process of generating a model response from a user input.
Every request consumes computing resources, so response speed and infrastructure cost matter immediately.
At small scale, a simple API integration may work well. As usage grows, the same design can become expensive and latency-sensitive.
- Small scale
- Growing usage
For an AI product manager, inference optimization connects user experience with operating margins.
The goal is infrastructure that stays responsive as an application grows from hundreds of users toward millions.
Quantization Saves Model Resources
Quantization reduces the numerical precision used to store model weights.
Lower precision requires less memory, which can make inference more efficient and reduce operational costs.
Think of model weights as stored numerical values. Quantization represents those values with a smaller numerical format, allowing hardware to handle more work within its available memory.
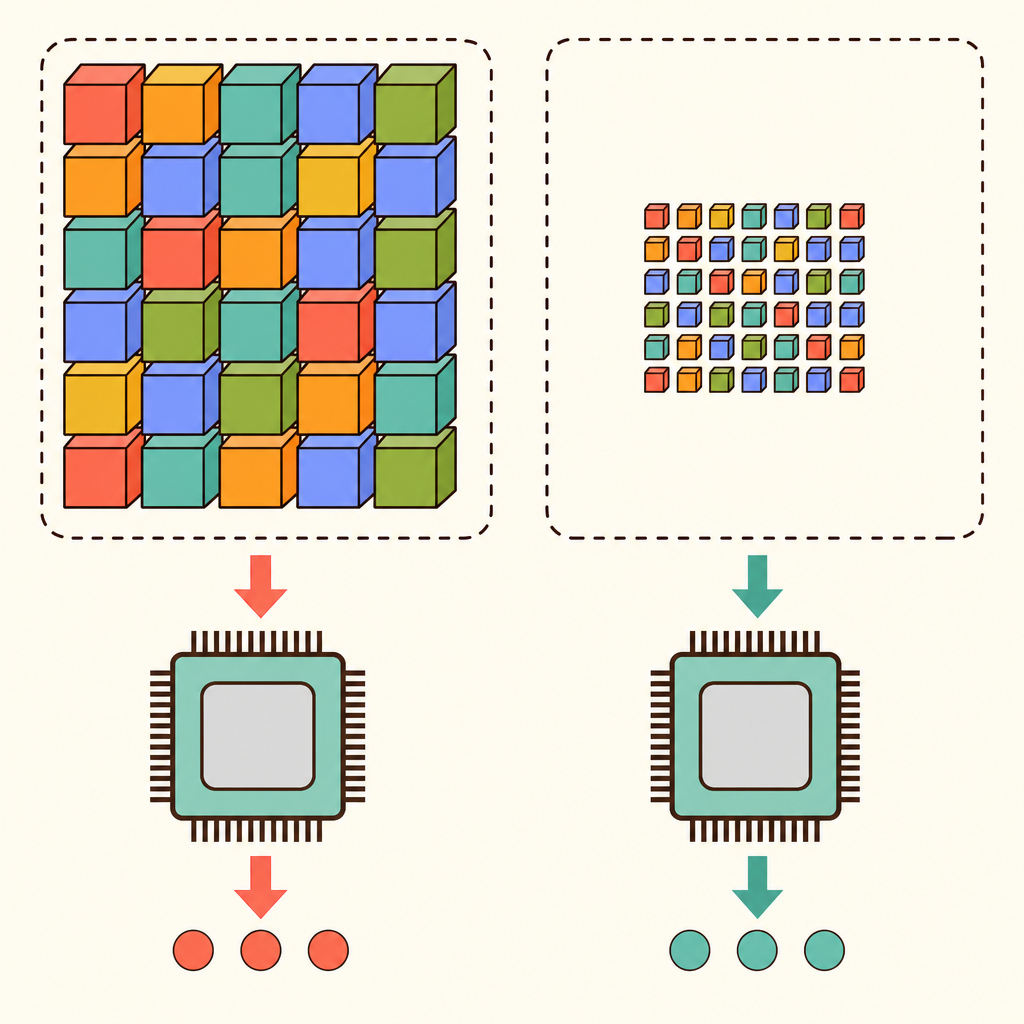
This technique changes how the model is stored and processed, while preserving its core function.
Teams should validate response quality after quantization before using it in production.
Batch Requests For Throughput
Dynamic batching groups multiple incoming requests so hardware can process them together.
Without batching, hardware may handle each user request separately, leaving useful capacity unused between operations.
With batching, several users can share one processing cycle. This increases hardware throughput and can lower the cost per request.
The system must still manage waiting time carefully. A larger batch may improve efficiency, while delaying a request can increase perceived latency.
- Without batching
- With batching
For product teams, throughput and responsiveness must be measured together.
Plan For Production Scale
Quantization and batching address different constraints. Quantization reduces the memory burden of the model, while batching improves how efficiently hardware handles requests.
- Quantization
- Batching
Together, they help an inference system support growth without immediately multiplying infrastructure costs.
Use these levers when moving from a successful prototype to a production-grade product. Track response latency, request volume, hardware usage, and operating cost.
Design for sudden traffic spikes, not only average demand. A system that serves hundreds of users comfortably may need stronger controls before reaching millions.
This technical intuition helps leaders project margins with greater confidence.
Inference Optimization at a Glance
Check yourself
What does inference mean in an AI product?
- Generating a model response from user input
- Training a model on labeled examples
Answer: Generating a model response from user input
Inference means generating a model response from a user input. It consumes computing resources, so speed and cost matter for every request.
Word pool: memory burden; throughput. Quantization lowers the model's _____, while dynamic batching improves hardware _____.
Answer: Word pool: memory burden; throughput. Quantization lowers the model's memory burden, while dynamic batching improves hardware throughput.
Quantization lowers the model's memory burden by using lower numerical precision. Dynamic batching groups requests so hardware can process more work together, improving throughput.
What does quantization change in an inference system?
- It groups incoming requests into shared processing cycles.
- It reduces the numerical precision used to store model weights.
- It increases request waiting time to improve response quality.
- It eliminates the need to measure infrastructure costs.
Answer: It reduces the numerical precision used to store model weights.
Quantization reduces memory use by representing model weights with fewer numerical bits. Because this can affect response quality, teams should validate quality before production use.
Keep going
This is lesson 1 of 4 in Scaling LLM Applications and Infrastructure. Next up:
- Context Management
- Pipeline Resilience
- Vector Databases
Wondering turns any topic into short lessons you can read, watch, or listen to, with practice questions and an AI tutor.