Free sample lesson · RLVR Foundations for AI Careers
RLVR Basics
What if an AI could prove its answer is correct every single time?
Lesson 1 of the Wondering course RLVR Foundations for AI Careers
The Shift to Objective Truth
Traditional AI training often relies on human feedback. This is subjective and can lead to errors.
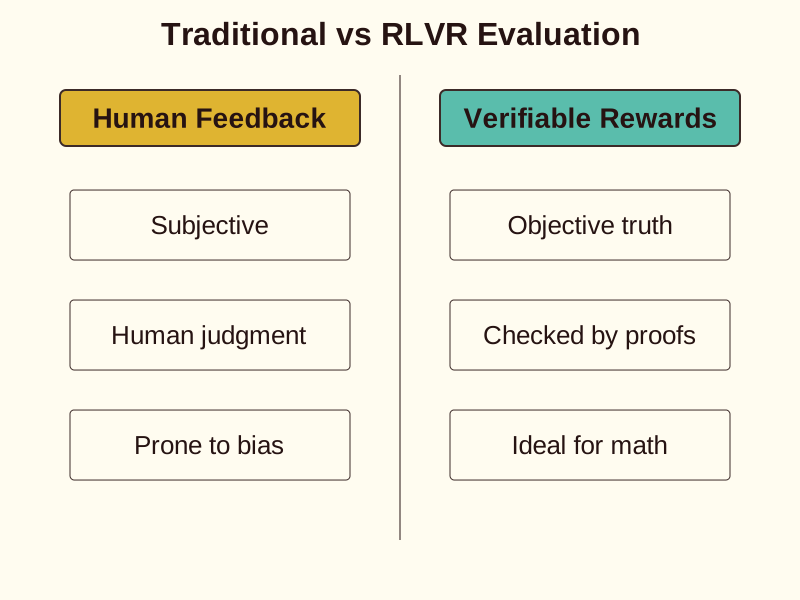
Reinforcement Learning from Verifiable Rewards (RLVR) changes this approach.
Instead of asking a human if an answer looks good, RLVR uses objective truth to grade the AI. This is essential for technical fields like math and coding.
How Verifiable Rewards Work
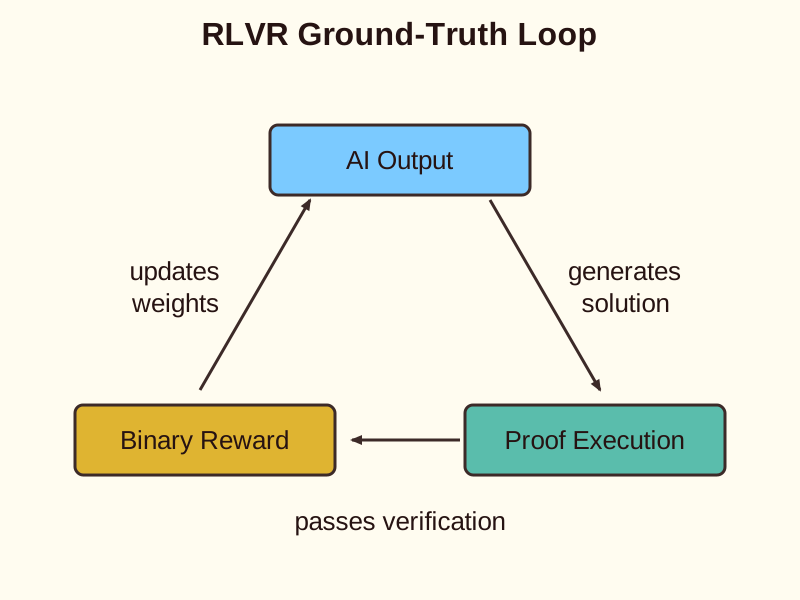
In RLVR, the reward signal is binary and indisputable. The answer is either proven correct or it is not.
Think of a math problem. A computer can run a formal proof to check the logic.
If the proof passes, the AI receives a reward. This creates a ground-truth feedback loop that does not rely on guessing.
Solving the Hallucination Problem
AI models often hallucinate by providing confident but false information. This happens when they prioritize sounding human over being accurate.
- Human Feedback
- Verifiable Rewards
RLVR forces the model to optimize for mathematical correctness.
By training on verifiable logic, we build systems that are reliable for mission-critical engineering and science applications.
Building Your AI Career
Mastering RLVR allows you to build agents that actually solve problems within a framework of correctness.
This skill is vital for transitioning into high-level AI development roles.
- Master RLVR: Understand verifiable reward functions and ground-truth verification.
- Build Agents: Create AI agents that operate within strict frameworks of correctness.
- Deploy Safely: Deliver scientifically sound AI systems for engineering and science.
You will move beyond simple chatbots. Instead, you will create capable AI deployments that are safe and scientifically sound.
How to Apply RLVR in Your AI Projects
- Define Ground Truth: Establish an immutable mathematical or logical condition that the output must satisfy.
- Automate Verification: Write an execution script or formal proof checker to test the AI's generated response programmatically.
- Reinforce Correctness: Provide a binary reward only when the verification passes successfully.
Check yourself
In Reinforcement Learning from Verifiable Rewards (RLVR), the AI's output is evaluated against _____ to determine correctness.
- objective logical truth
- human quality preferences
Answer: objective logical truth
RLVR replaces subjective human opinion with objective mathematical or logical ground truth to grade the AI's answer.
While traditional AI training uses _____ human feedback, RLVR provides a _____ reward signal based on mathematical proofs.
Answer: While traditional AI training uses subjective human feedback, RLVR provides a binary reward signal based on mathematical proofs.
Traditional methods rely on subjective human preferences, whereas RLVR uses indisputable binary feedback—either the proof passes or it fails.
How does Reinforcement Learning from Verifiable Rewards (RLVR) directly address the AI hallucination problem?
- By penalizing unverified outputs and forcing optimization for mathematical correctness.
- By rewarding conversational fluency and natural language sound.
- By increasing the number of human reviewers during model training.
- By training the model on a larger dataset of unverified text.
Answer: By penalizing unverified outputs and forcing optimization for mathematical correctness.
AI models hallucinate when they prioritize sounding natural over being accurate. RLVR counters this by requiring outputs to adhere strictly to verifiable logical and mathematical rules.
Keep going
This is lesson 1 of 5 in RLVR Foundations for AI Careers. Next up:
- Verifiable Rewards
- Environment Setup
- Model Training
- Portfolio Building
Wondering turns any topic into short lessons you can read, watch, or listen to, with practice questions and an AI tutor.