Free sample lesson · Deep Dive Into LLMs Like ChatGPT
Three Training Stages
How does a neural network learn to be a helpful assistant?
Lesson 1 of the Wondering course Deep Dive Into LLMs Like ChatGPT
Three Stages Of Learning
How does a neural network learn to become a helpful assistant? It passes through three training stages that build on one another.
First, pre-training reads internet documents. Next, supervised fine-tuning teaches assistant behavior. Finally, reinforcement learning gives the model problem-solving practice.
- Pre-training: The model reads internet documents to build broad knowledge.
- Fine-tuning: Human-labeled conversations teach the model helpful assistant behavior.
- Reinforcement learning: Practice solving problems helps the model improve its strategies.
This resembles human education: read textbooks, study worked solutions, then solve practice problems. Each stage adds a different ability.
Building The Base Model
Pre-training creates the base model by learning patterns from internet documents.
At this point, the model simulates those documents. It is not yet a useful assistant because it has not learned how to respond helpfully.
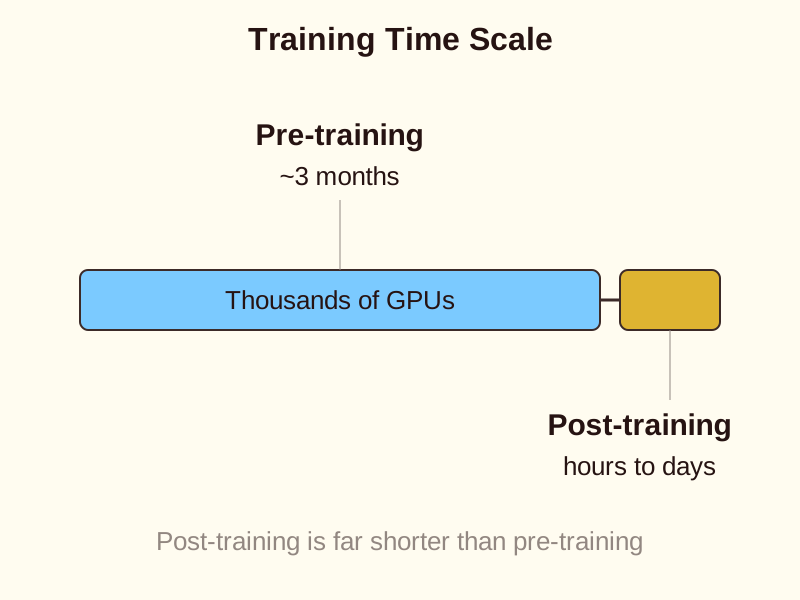
The timeline shows the scale: pre-training takes about 3 months, while post-training may take hours to days. Thousands of GPUs perform this demanding work.
Teaching Helpful Behavior
Supervised fine-tuning trains the base model on human-labeled conversations.
People provide examples of useful assistant responses. The model learns to follow instructions, answer questions, and communicate in a helpful format.
The cost comparison is dramatic: pre-training costs millions of dollars, while post-training is much cheaper. This makes targeted behavior improvements practical after the base model exists.
- Pre-training
- Post-training
Practicing Problem Solving
Reinforcement learning lets the model practice solving problems and discover effective strategies.
It comes after supervised fine-tuning, so the model already knows how an assistant should behave. Practice then helps it improve its approach to challenging tasks.
Together, the stages explain the final system: pre-training supplies broad knowledge, fine-tuning shapes behavior, and reinforcement learning strengthens problem-solving. Each stage is essential.
Check yourself
Pre-training creates a base model by learning patterns from _____.
- internet documents
- human-labeled conversations
Answer: internet documents
Pre-training reads vast amounts of internet documents to build broad language patterns, whereas human-labeled conversations are introduced later during supervised fine-tuning.
In the AI training process, _____ takes about 3 months, while _____ takes only hours to days.
Answer: In the AI training process, pre-training takes about 3 months, while post-training takes only hours to days.
Pre-training requires months of processing on thousands of GPUs, whereas post-training (fine-tuning and reinforcement learning) is much faster and cheaper.
Why does reinforcement learning occur after supervised fine-tuning instead of before it?
- It ensures the model already knows proper assistant behavior before practicing complex problem solving.
- It reduces the financial cost of running pre-training across thousands of GPUs.
- It supplies the initial broad knowledge needed to understand raw internet documents.
- It generates human-labeled conversation examples automatically.
Answer: It ensures the model already knows proper assistant behavior before practicing complex problem solving.
Supervised fine-tuning first teaches the model basic assistant behavior and instruction-following. Once it knows how to act like an assistant, reinforcement learning allows it to practice and discover effective problem-solving strategies.
Keep going
This is lesson 1 of 20 in Deep Dive Into LLMs Like ChatGPT. Next up:
- Internet Data Curation
- Tokenization Fundamentals
- Neural Network Training
- Base Models Explained
- Text Generation Process
Wondering turns any topic into short lessons you can read, watch, or listen to, with practice questions and an AI tutor.