Free sample lesson · Debugging Production-Scale Spark Pipelines
Data skew and why 1% samples miss it
Lesson 1 of the Wondering course Debugging Production-Scale Spark Pipelines
When a few keys carry everything
In distributed processing, work is split by key. Each key lands on a worker, and the assumption is that the load spreads evenly.
Reality rarely cooperates.
A small number of keys or sessions often carry a disproportionate share of the volume. That imbalance is called data skew, and it decides whether a job finishes or falls over.
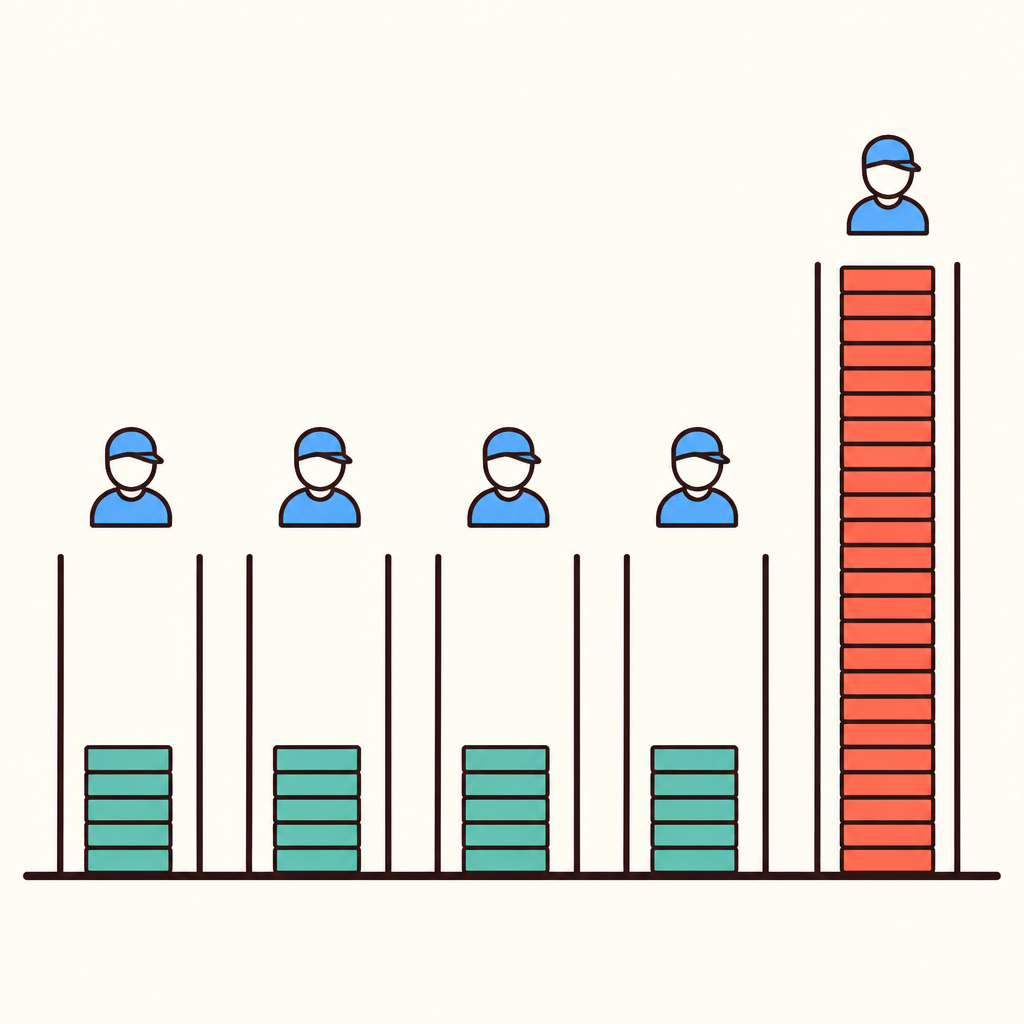
Notice that most partitions hold a thin stack of events while one partition holds a towering stack, which is the shape data skew creates.
The idle streaming session
Picture event logs from a streaming service.
A typical viewing session produces a handful of events: play, pause, seek, stop.
Now picture a session left idle on a paused screen. It can keep emitting heartbeat and status events until it has generated tens of thousands of records under a single session key.
Same schema. Same pipeline. Wildly different weight.
- Typical session
- Idle session
Why sampling advice exists
Standard testing wisdom says to work on a small sample. Pull 1% of production data, run the pipeline, check the output.
For logic bugs, this works well.
A wrong join condition, a bad null handling rule, or a mistyped field breaks on almost any record. A small sample surfaces it quickly and cheaply.
- Pull sample: Take roughly 1% of production data.
- Run pipeline: Execute the same job over the reduced dataset.
- Check output: Inspect results for wrong joins, nulls, or mistyped fields.
- Fix logic: Logic bugs break on almost any record, so the sample exposes them.
What a 1% sample throws away
Sampling picks records at random. That is exactly the problem.
The long tail is rare by definition. A 1% sample is overwhelmingly likely to strip out the heavy session keys entirely, or keep only a thin slice of one.
Your sample looks perfectly balanced. Production is not.
- Common enough to be sampled
- Play, pause, seek, stop
- Rare by definition
- Idle session with tens of thousands of events
- Usually missing from the sample
- Only part of one heavy key survives
- Looks balanced in the sample
The failures that only appear at scale
Skew does not break correctness. It breaks scale and performance.
A single oversized key can exhaust a worker's memory and trigger an OOM. It can force shuffle spillage when data no longer fits in memory during redistribution.
When a task dies, the whole stage retries. Then it fails the same way again, because the same key is still oversized.
- Oversized key: One session key carries tens of thousands of events.
- Fits in memory?: The worker tries to hold the key's data during redistribution.
- Shuffle spillage: Data no longer fits in memory during redistribution.
- OOM: The worker exhausts its memory and the task dies.
- Stage retry: The whole stage restarts after the task dies.
- Same failure: The key is still oversized, so the job fails again.
- task dies
- retries same key
Match the sample to the bug
The lesson is not that sampling is wrong. It is that the sample must match the bug you are hunting.
Chasing a logic bug? A random 1% is fine.
Chasing an OOM, shuffle spillage, or repeated stage retries? You need the heavy keys deliberately kept in, because those records are the whole point.
Key takeaways
Skew means a few keys carry most of the volume, like one idle session with tens of thousands of events.
Random sampling removes exactly those records.
So a clean run on 1% proves your logic works. It proves nothing about whether the job survives production.
Check yourself
Data skew occurs when a small number of keys carry a disproportionate share of the processing volume.
- True
- False
Answer: True
This is data skew: the work is not evenly distributed because a few keys hold much more data than the rest.
An oversized key can exhaust worker memory and cause _____, trigger _____ during redistribution, and produce repeated _____.
Answer: An oversized key can exhaust worker memory and cause OOM, trigger shuffle spillage during redistribution, and produce repeated stage retries.
OOM occurs when a worker runs out of memory. Shuffle spillage occurs when redistributed data no longer fits in memory. If the same oversized key remains, the stage can fail and retry repeatedly.
A streaming pipeline normally sees sessions with a handful of events, but one paused session produces 30,000 heartbeat and status records under one session key. What does this illustrate?
- Data skew caused by a heavy key
- A logic bug caused by a wrong join condition
- Uniform distribution across workers
- A null handling error affecting every record
Answer: Data skew caused by a heavy key
The paused session concentrates an unusually large amount of data under one key, while typical sessions remain small. That imbalance is data skew.
Keep going
This is lesson 1 of 9 in Debugging Production-Scale Spark Pipelines. Next up:
- When you must test against full, unsampled production data
- Branch-driven isolation for concurrent experiments
- Using tmux for session persistence on remote dev boxes
- Delegating experiment ops to an AI agent
- collect_list and per-row memory bloat
Wondering turns any topic into short lessons you can read, watch, or listen to, with practice questions and an AI tutor.